Each activity is a self-contained security engagement with its own report shape. Run one, or run several together. They execute concurrently against the same target, through whichever coding agent you already use.
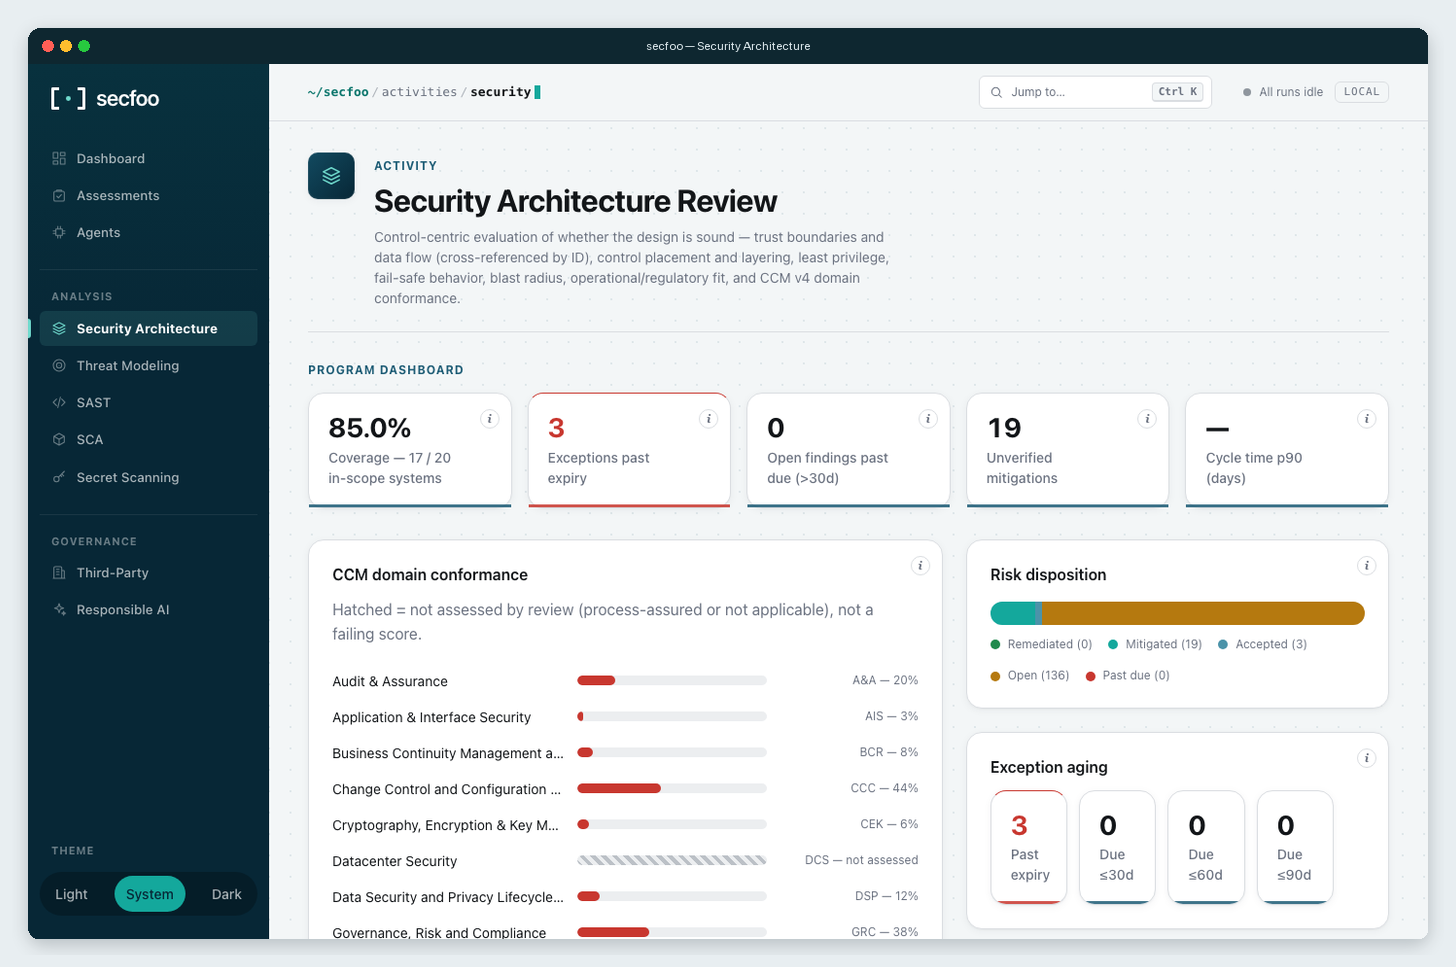
Controls matrix (presence, placement, layering), a design-principles verdict, operational & regulatory fit, CSA CCM v4 domain conformance, and a Design verdict for milestone gating.
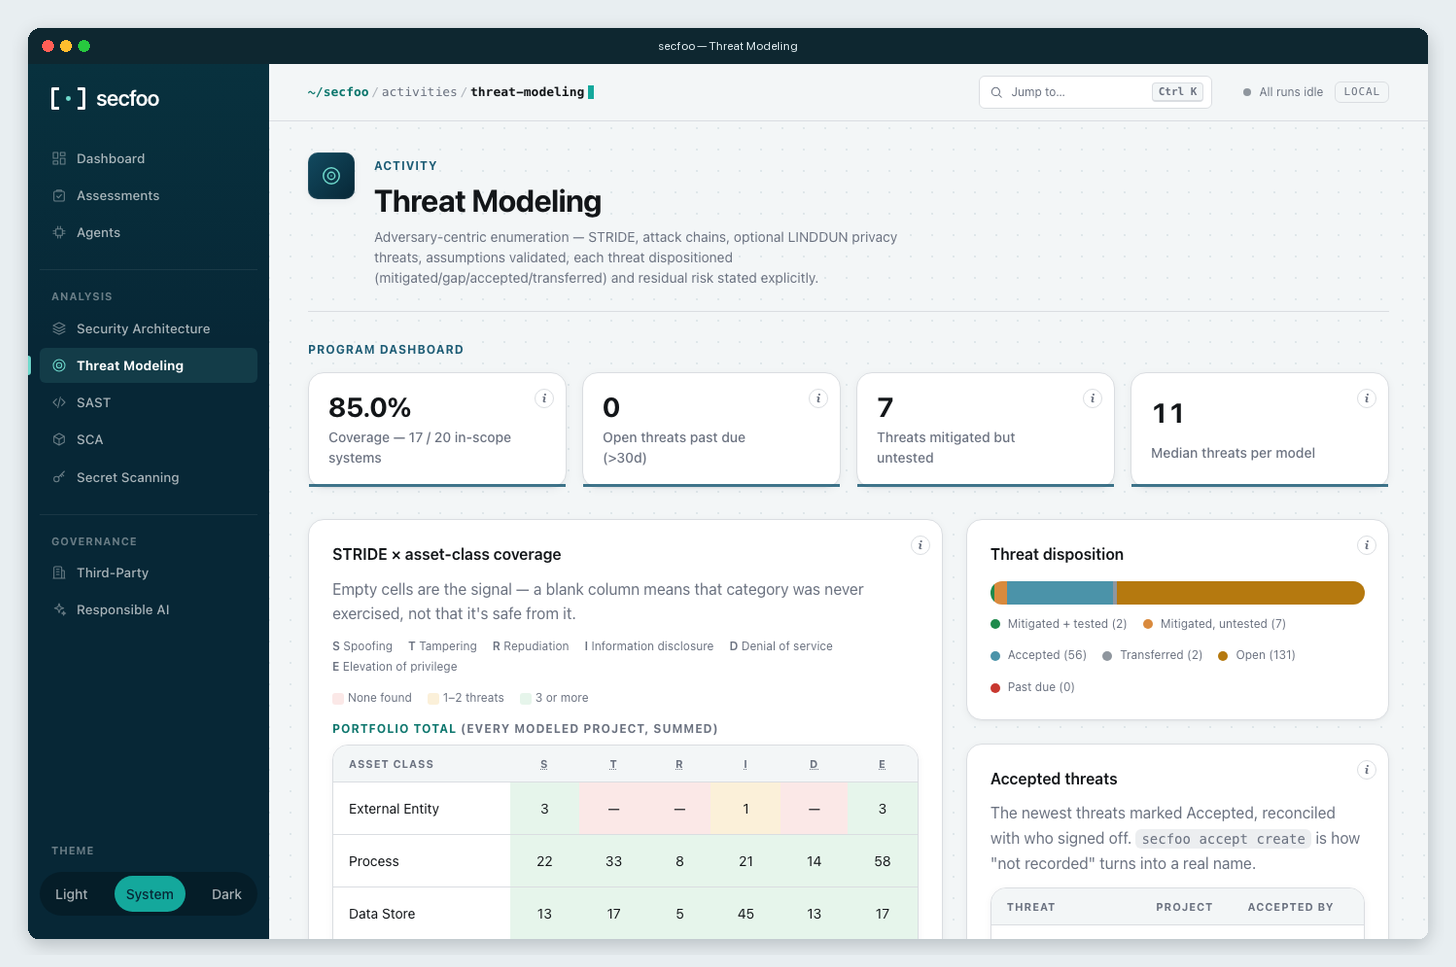
Adversary classes, STRIDE (+ LINDDUN when personal data is in scope), attack chains, every threat dispositioned Mitigated / Gap / Accepted, and an explicit residual risk statement.
Code-level findings with taint paths, CWE/OWASP mapping, and illustrative fix diffs. The agent states a CVSS v3.1 vector; Secfoo computes the base score from it with FIRST.org's published formula.
Dependency inventory, a reachability verdict per risk, and a grouped upgrade plan. Package versions are checked against OSV.dev, so advisories come from a real database and the model is never asked to invent a CVE ID.
Exposed credentials across source, config, git history, and linked Confluence pages, with a rotation-first remediation list.
LLM prompt, tool-definition, and agent-behavior security review.
Production security and operational readiness review.
Governance, transparency, fairness, and oversight review — drives the dashboard's Responsible AI risk badges.
These two look adjacent but answer different questions and fail differently, so Secfoo keeps them separate rather than merging them into one "threat assessment."
Asks is this design sound? Are controls present, correctly placed, and layered? Is least privilege enforced by the topology or merely by policy? Does the design fail safe? It also covers ground with no attacker at all: recoverability, key lifecycle, maintainability, regulatory fit.
Asks what could go wrong, and who would make it go wrong? Enumerate threats from assets and trust boundaries, then disposition each as mitigated, accepted, or a gap, and state residual risk explicitly.
An architecture review can pass every checklist item and still miss a threat nobody enumerated. A threat model can list fifty threats and still miss that the design has no blast-radius containment. Run both.
Secfoo drives a coding-agent CLI that's already installed and logged in on your machine, or calls a model directly with an API key. Pick one with --agent, choose a model with --model or a per-agent default in config, and run secfoo agents to see what's on your PATH.
| Agent ID | Runs with | Model selection | Notes |
|---|---|---|---|
claude | Claude Code | ✓ | Read-only tool grant. MCP servers from your Secfoo config load automatically and nothing else does. Reports cost. |
agent | Cursor | ✓ | MCP via secfoo mcp sync. |
codex | Codex CLI | ✓ | Runs in Codex's read-only sandbox. Reports token usage. |
copilot | GitHub Copilot CLI | ✓ | Copilot auto-approves tools, so read-only relies on the review instructions, not a sandbox. |
gemini | Gemini CLI | ✓ | MCP via secfoo mcp sync. Reports token usage. |
opencode | OpenCode | ✓ | Shell, edit and web-fetch permissions denied for the run. Reports cost. |
droid | Factory Droid | ✓ | Set FACTORY_API_KEY for non-interactive runs. |
agy | Antigravity | — | Headless mode denies tool calls that need approval. |
devin | Devin CLI | — | Log in first with devin auth login. |
api | OpenAI, Anthropic or Gemini API key | ✓ | No agent CLI needed: pip install "secfoo[api]". Source files are sent in the prompt. Cost comes from LiteLLM. |
Setup and troubleshooting for each one: Agent setup guide →
Each focused activity gets its own program page. Architecture and threat-modeling views are built from what a report can state at review time and the exceptions you record. SAST, SCA and secret findings carry an open/closed lifecycle across rescans. Approximations are labeled, never guessed.


A SAST or secret finding's identity is its CWE or secret type, the file, and a hash of the source around the reported line. An agent rephrasing a title doesn't create a duplicate, and two issues in one file stay distinct.
After each run, findings that reappear stay open and findings that don't are closed. SCA findings are keyed by package and advisory, so a version bump that doesn't fix the issue keeps it open.
Every run records the git commit it scanned. Rerun the same commit on a terminal and Secfoo asks first; --rescan scans anyway. CI runs always scan.
secfoo findings export writes open findings, with language, framework and a code-free description of the vulnerable construct. --format sarif produces SARIF 2.1.0 for GitHub code scanning; --no-locations strips paths.
secfoo findings export # open findings, JSON Lines
secfoo findings export --format sarif --project 1 -o findings.sarif
secfoo cost --by skill --since 2026-09-01 # AI spend across past runs
An Application ID / Security Assessment Request, a review status, and one or more attached runs or uploaded files — like an AI-BOM inventory. The Assessments, Third-Party, and Responsible AI dashboard pages are all built on top of it.
secfoo assessment create \
--project https://github.com/org/vendor-app \
--type third-party --app-id APP-042 \
--sar SAR-2026-0007 --reviewer "Jane Doe"
secfoo run --skill security-architecture-review \
--agent claude --assessment 1